Plan mode, enforced
By Ian Provencher
This is the planning half of how I work with Claude Code. It ends with an approved plan and a fresh window that builds it while I am away. The proof half, The completion meter, is how that window knows when it is finished. From plan to proof traces one job through both.
I first wrote this up on 12 October. The rules changed on five days between 19 October and 29 October, so this version describes the setup as it runs on 31 October. The 12 October record is kept in the story, labelled with its date, where it explains a rule.
What Anthropic’s guide says now
Anthropic has rewritten its Claude Code best practices since my first version. New terminal and VS Code sessions now start in auto mode, “where a classifier reviews anything risky before it runs”, and the page no longer mentions plan mode. The interview and the fresh session are still there:
Ask Claude to interview you instead
Once
SPEC.mdexists, start a fresh session to build from it, so the build begins with a clean context and a written definition of done.
The page now also sorts every instruction into two kinds. A prompt, a CLAUDE.md or a skill is read by the model, and “The model then decides what to do with this information.” A hook, a deny rule or a managed setting is carried out by Claude Code itself, which “applies this every time, no matter what the model decided to do.”
That split is the design brief for everything below. The interview is still advice the model reads. Whether planning happens, whether a decision reaches me in a form I can answer, whether a plan can be approved half-written, and when the build stops are all held by hooks and code.
The pipeline, as of 31 October
- Plan mode is the default, so every session starts read-only.
- A prompt hook loads the interview method on the first planning turn.
- A helper hook refuses every change to the machine while research helpers are out.
- A question hook refuses any decision box I could not answer well.
- A save hook prechecks a sealed plan and lists everything the exit would refuse.
- An exit hook refuses to leave plan mode until the plan is sealed, every item carries a proof that can fail, and the plan matches my watch-or-walk answer.
- A handoff hook opens a fresh auto-mode window with
/goalalready set. - The completion meter, a mod, counts the plan in code, and the
/goaljudge reads the one line it prints.
Scroll the stages below. The panel follows you and shows this post’s own planning session at each stage: the mode, the window doing the work, where the session was, the exit gate, the context in the working window and the tokens read so far across both windows.
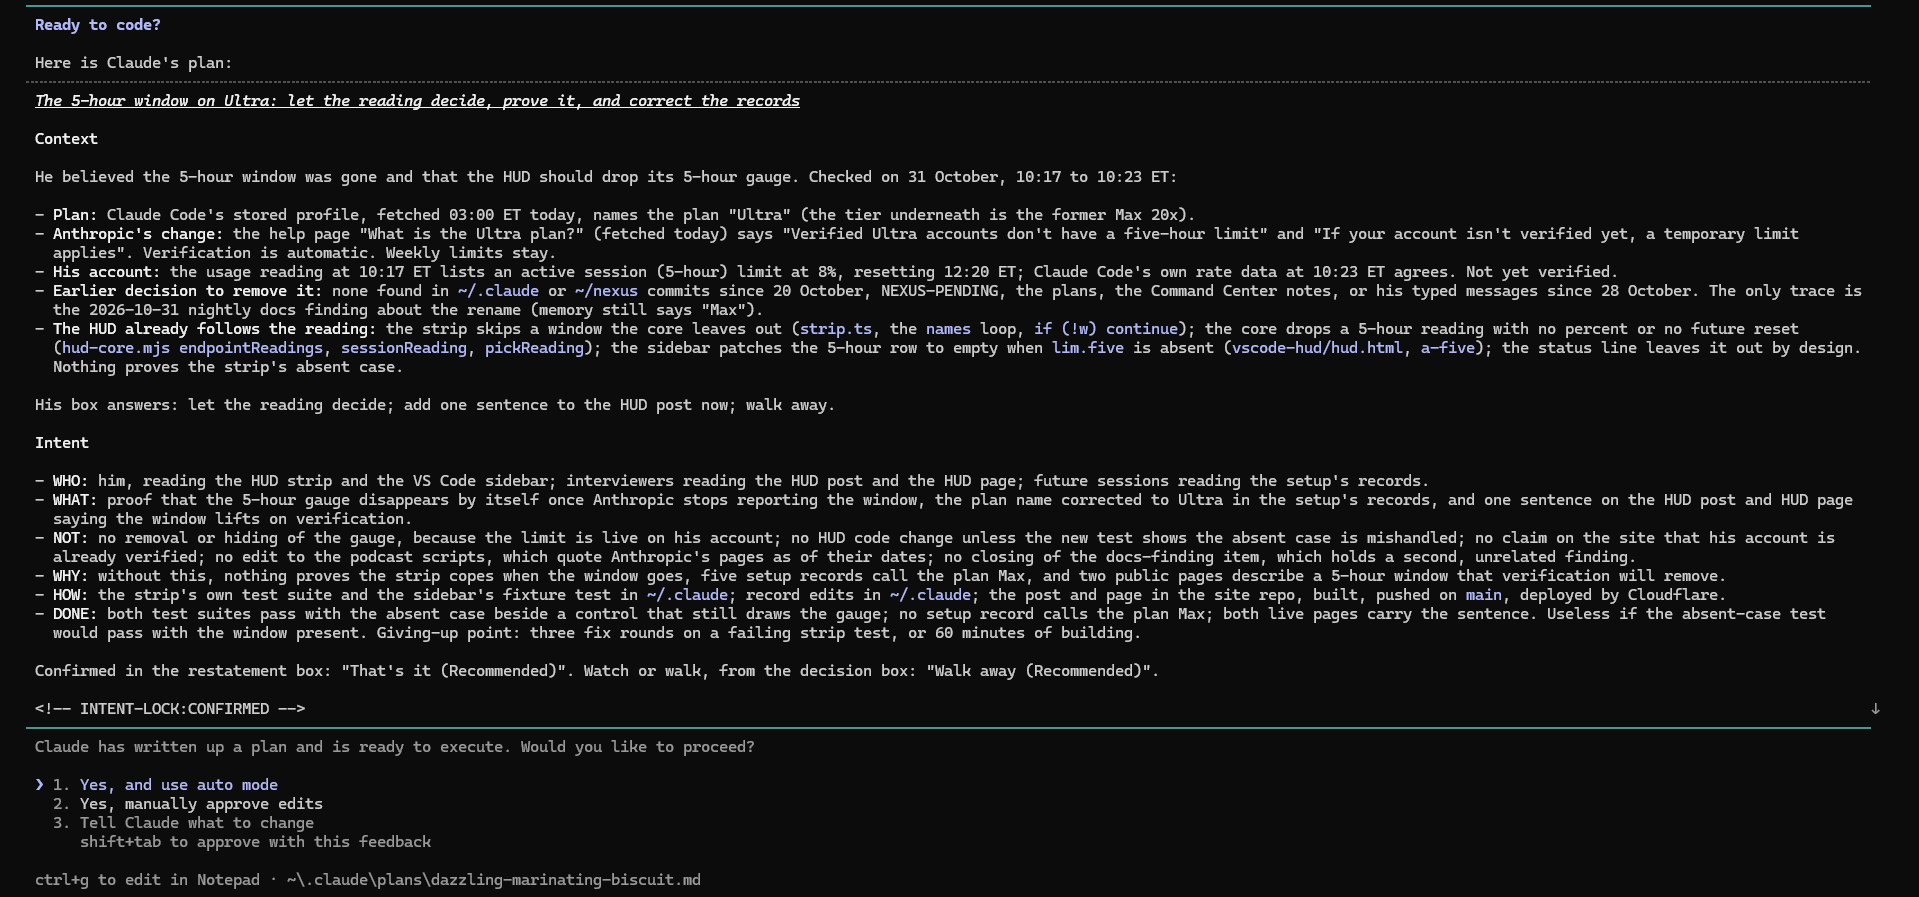
-
01 Plan mode is the default
SettingEvery session starts in plan mode. Nothing is pressed to get there, and nothing changes the machine until a plan is approved.
// ~/.claude/settings.json
"permissions": {
  "defaultMode": "plan",
  ...
One setting does it. In plan mode Claude reads, searches and asks, and every write or command that changes the machine needs an approved plan first. Anthropic's guide now starts new sessions in auto mode, where a classifier reviews anything risky before it runs. This setup overrides that default, and every stage below decides when plan mode ends.
This post was planned in one such session. Its first prompt went in at 01:48 ET, and the panel follows that session and the build it handed to.
-
02 The method loads
Enforced by a hookBefore Claude plans anything, a hook puts the interview method into its context.
UserPromptSubmit → intent-inject.shpermission_mode = "plan" ✓ · not a headless run ✓first send this session ✓ → the whole methodstdout → Claude's contextClaude Code runs the hook on every prompt and hands it a JSON payload. The hook acts only when
permission_modeis"plan", and since 6 October it skips headless runs, which have nobody to interview. The whole method goes out once per session, and later prompts get a short reminder.Size matters here. Past 10,000 characters, Claude Code shows the session a 2 KB preview and a file path instead of a hook's output. The method crossed that line on 6 September, and every planning session until 30 September got only the preview. Since 26 October a guard refuses any commit that grows the method to 10,000 characters or more. As of 31 October it is 9,671.
-
03 Calibrate, then design from zero
InstructedClaude sizes the interview to the ask and says which branch it took, so a wrong call costs one word to fix.
- Fewer than three open unknowns — one confirming sentence naming
  what is assumed, then proceed. No interrogation.
- Three or more — full rounds until the ledger empties.
A method that interrogates a typo fix gets switched off, so the short branch matters as much as the long one. On the long branch, the order changed on 25 October. First Claude asks what the code cannot answer: who it is for, why, and what it is not. Then it designs the best mechanism from the objective alone, before reading what the build would touch. Only then does it explore, holding what exists against that design.
The order is the point. Read the code first and the design becomes a patch on whatever is there.
-
04 Helpers search, and nothing changes
Enforced by a hookHelpers map the code in parallel. While any is out, a hook refuses every change to the machine.
3 helpers out at 01:51 ETa command startingnpmat 01:52 ET refusedreading still open: ls, cat, grep, git log, git diff …all back at 02:00 ET changes openA helper is a subagent with its own context, and only three read-only kinds may launch: one that searches, one that reviews when asked, and one that answers questions about Claude Code. At most four run at once, and none can start another. The hook writes a marker when a helper starts and removes it when the helper reports. While any marker stands, every file write and every command off a short reading list is refused, by every tool.
It exists because a session once rewrote a stylesheet, committed and pushed it thirteen minutes before its own research landed. The refusal in the panel's session is real: one command started with
npmwhile the helpers were out. The build that wrote this post hit the same hook 2 time(s), each while its own helpers were mapping the code. -
05 The question box, five beats
Enforced by a hookEvery decision arrives as a box of options. A hook reads the whole box before it is drawn and refuses one I could not answer well.
1 · What happens · in my words, not the machinery's2 · How it differs · opens with "Unlike"3 · What I will see4 · The cost in numbers · minutes of the session, then mine5 · What that cost means for meA
PreToolUsehook onAskUserQuestionreceives every question and option before the box draws, and a refusal sends its reason back to Claude, which rewrites the box. It refuses a file name, a code identifier or a flag in a header or label. It refuses an option shorter than five sentences, because each option owes five beats, one sentence each. That was four beats until 25 October, when the cost moved from "what you give up" to a number with its meaning beside it.qg_ns = gsub(/[.!?]"? /, " ", qg_t) if (text ~ /[.!?]"?$/) qg_ns++ if (qg_ns < 5) flag(kind, qi, "... it needs five beats, one sentence each ...")
It counts sentence endings and never grades the writing. The panel's session asked 11 questions in 4 boxes.
-
06 The ledger, tensions first
InstructedA numbered list of what is still open, shown every round. Tensions outrank assumptions, because resolving one usually changes the build.
tension · an answer that sits badly against another answer, the goal or the codeassumption · something taken on faiththe gate opens when the list is empty, or every survivor is a risk I accepted by nameThe floor is two rounds on the long branch. A first round returns answers nobody has had time to be surprised by, and the second is spent on what the first opened. This is instructed rather than counted: the skill says it, and the seal at the end is the record the gate checks.
This stage is unchanged since 12 October.
-
07 The restatement, inside the box
Enforced by a hookBefore sealing, Claude restates the whole intent inside the question box and asks me to break it.
box 3, the restatement in the question itself"Here is the build. Break anything that's wrong. …"my answer · That's itFrom the 12 October record. Rounds three and four of that session asked whether "the restatement above" matched what I wanted, and in round four I answered: "I never ever see the statement you ask me about every time we get to this point of the workflow. I NEVER see it." The build window then ran a real Claude Code session in a virtual terminal. The box drew 23 rows, and on a 30-row screen the paragraph's opening line was off the top. On a 60-row screen, the control, it was visible.
So the restatement goes in the box's question field, and the question hook refuses a box that points at reply text: "the restatement above", "listed above", "in my reply". On 29 October that rule was narrowed. Of 27 pointer findings in the ten days before, 16 pointed at the reply and 11 did not. A promised later reply now passes, and so do "the table above", ordinary uses of "above", and an option's "Unlike the … above". A vague pointer at another part of the same box stays refused, and the refusal says to name that part by its label. Replayed over 1,470 boxes, findings went from 115 to 100, with none new.
-
08 Seal, proofs and From zero
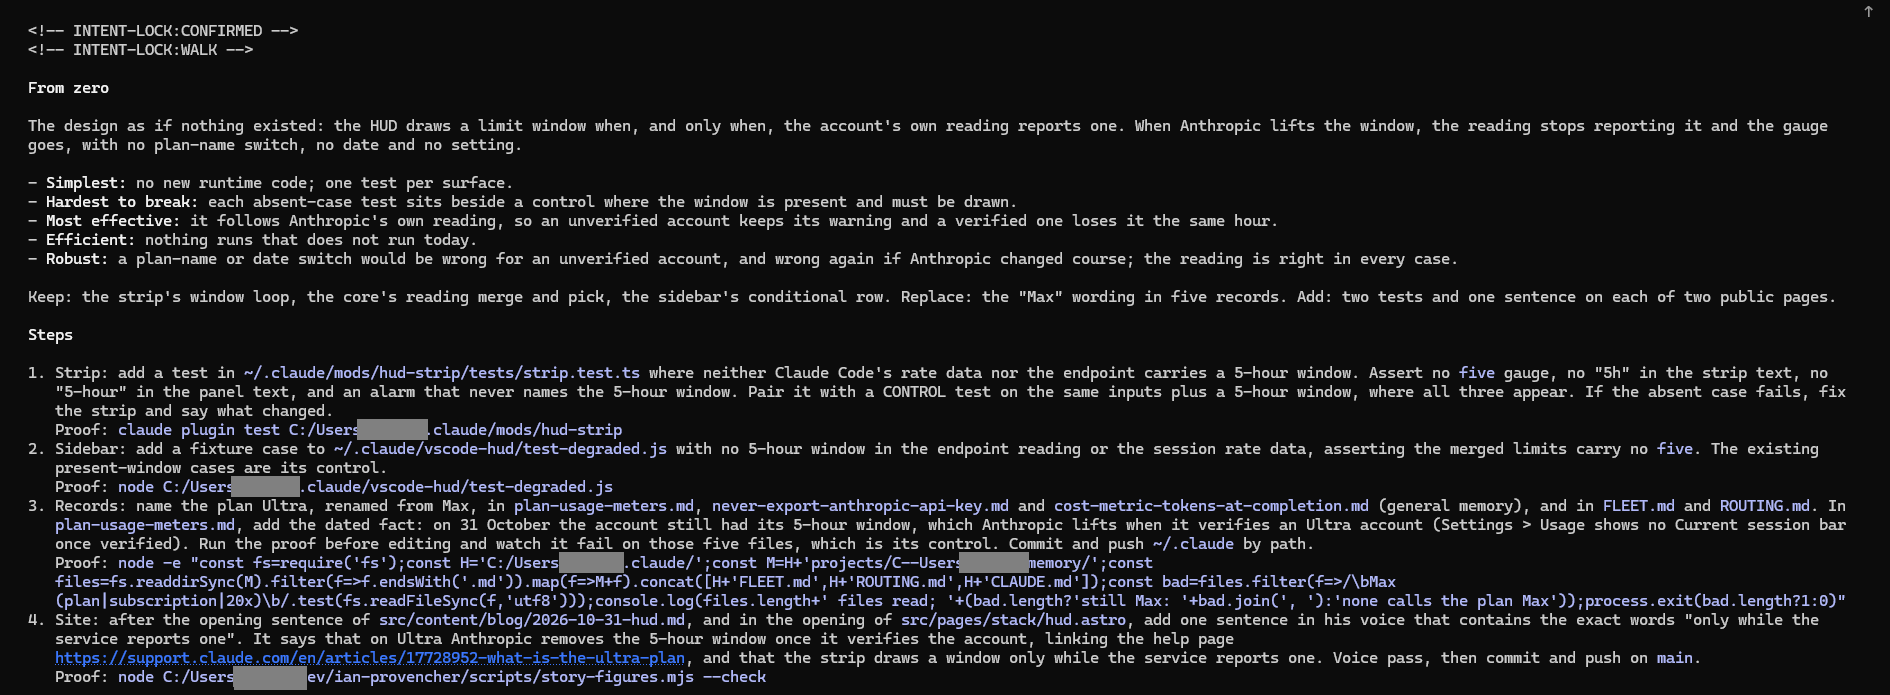
Enforced by a hookThe plan is sealed with the confirmed intent, and every item carries the command that proves it.
## Intent · WHO · WHAT · NOT · WHY · HOW · DONE<!-- INTENT-LOCK:CONFIRMED -->## From zero · the design as if nothing existed## Steps · ## Verification · each item ends Proof: `one whole command`Each proof is one whole command in backticks, and the item is proved when that command runs exactly as written and exits clean. Nothing in it may hide its exit code: no pipe, no
|| true, no leading!. Since 25 October a plan that builds also needs a From zero section, holding the design from the objective alone and a keep, replace or remove for each piece it touches.Since 23 October saving a sealed plan triggers a precheck. It runs everything the exit gate would refuse and hands the whole list back at once, so the first exit passes. It exists because 52 of 85 plans in the 30 days before were refused at least once at the exit. This post's plan was written once, at 07:40 ET.
DONE changed too. On 12 October it was evidence for the judge to find in the conversation. Now it is for me to read, and the items and their proofs are the checks.
-
09 Watch or walk
His callThe last question is whether I watch the build here or walk away and let a fresh window build it.
07:29 ET · Watch or walk? Watch07:33 ET · a judge while you watch? typed: "switch to a walk away build"07:40 ET · Walk away or watch? Walk awayThis session shows the rule working. I answered Watch, then typed a switch into the next box's free-text row. The gate counts an answer only from a box whose question offers both choices, and the box I typed into asked about the judge. So the session asked once more, and I picked Walk away. The answer is read from the box's recorded answers, never from its text, because that text repeats the question, which names both. The plan then carries
<!-- INTENT-LOCK:WALK -->, and the gate checks that line against my answer.Watching keeps the build in the planning window. Walking away arms the handoff.
-
10 The exit gate
Enforced by a hookClaude cannot leave plan mode until a hook has read the plan and found nothing to refuse.
no helper still outsealed, with an Intent of 40 words or morenumbered Steps and Verification, every item proved or marked mine or laterevery proof one whole command that can failFrom zero present · watch or walk matches my answerthe launcher can build the goalA
PreToolUsehook onExitPlanModeruns before the approval prompt is drawn. A proof line is refused when it stops at a backtick inside its own command, names no command, holds a placeholder in angle brackets, or cannot fail. Those proof rules live in one plan reader, the same code the completion meter counts with, so the gate and the count can never read a plan differently.If the gate cannot read what it needs, it lets the exit through. Since 26 October it also says on my screen, and to Claude, what went unchecked. This post's plan passed on its first exit, at 07:41 ET.
-
11 The handoff
Enforced by a hookI approve the plan, and a fresh window opens in auto mode with its first prompt already typed: a
/goalbuilt from the plan.PostToolUse · ExitPlanMode → the walk record for this exitClaude runs the launcher, in viewgoal · the plan's path and each step's first line · 2,500 charactersclaude --permission-mode auto --model … --session-id … --effort … "/goal …"opened ✓ · the new window's transcript shows the goal setThe walk answer leaves a record. The approval hook acts only for the exit and the plan that record names, matched by the exit call's own id since 26 October, so a stale record never fires on tomorrow's plan. It does not start a window behind Claude's back: it tells Claude its next and only action is one launcher command, so the launch lands in the transcript.
The launcher builds the goal from the plan's path and the first line of each step, as many as fit under the 4,000 characters
/goalaccepts. This build's came to 2,500. It reports the window opened only once the new window's own transcript shows the goal set. -
12 The judge reads the tally
Built into Claude CodeAfter every turn of the build, a separate model reads the conversation and decides whether the goal is met. Since 26 October the goal is one printed line.
... Done when the latest tally, printed with that tool after the last change,
ends with the line VERDICT: ALL DONE.
Anthropic's guide files
/goalunder the instructions the model decides, and says of any hook that asks a model: "Apromptoragenthook asks another model to decide, so it isn't deterministic either." That was true of the 12 October version, where the judge read the plan's DONE line and judged the evidence itself.Now the completion meter counts the plan in code, and the judge reads the tally's last line. The judge is still a model, but it no longer has to decide what "done" means. A plan with no item a command proves gets no goal at all. How the count works is the subject of The completion meter.
-
13 The whole bill
MeasuredBoth windows counted, against the same build run inside the planning window.
- The planning window sent 43 requests and read 8,888,211 tokens. Its last request carried 305,089.
- The build window started at 73,267 per request, its own setup, and to the cut sent 353 requests reading 93,534,584.
- Both together: 102,422,795.
- The same build in the planning window carries the interview on every request: 231,822 more each, 184,255,961 in all. The handoff read 81,833,166 fewer, 44.4% less.
Every request re-reads its whole context, so a window's cost is the sum of its context at every request. The fresh window's saving is in that re-reading, and the larger saving is the rework the interview moved earlier, to where it is cheapest.
Tokens here are each request's input, cache read and cache write, counted once per request from the two session logs, to the cut recorded in the figures file.
In action
What changed since 12 October
- 19 October. Every plan item ends with the command that proves it, and the exit gate refuses a plan without one.
- 23 October. A sealed plan is prechecked when it is saved, and the watch-or-walk answer is read from the last decision round instead of only after the seal.
- 25 October. Options carry five beats, with cost as a number. A building plan needs a From zero section, and the method designs before it explores. Helpers became three read-only kinds that can never build.
- 26 October. The walk-away goal became the completion meter’s tally. The handoff fires only for the exit that armed it. A guard holds the method under the size Claude Code will show whole, and a gate that lets something through unchecked now says so.
- 29 October. The rule against pointing at reply text was narrowed to what a reader actually cannot see.
Take it
The kit is public: github.com/AceP2317/intent-lock. It holds the interview skill, the question rules and four hooks: the method loader, the question guard, the exit gate and the handoff. It is a lighter cut of what runs here, and it has fallen further behind since 12 October. Its exit gate reads the plan’s own watch-or-walk line instead of my answer in the transcript, it has no helper hook, and its handoff still builds the goal from the plan’s DONE line, because the kit has no meter to count against.
Its test suite runs every hook against fixtures in both directions, and every refusal has a twin that must pass. As of 31 October it runs 87 checks. Since that day it also reports a check it had to skip as skipped, because until then a machine missing a tool printed the same total as one that ran everything.